5 Tips for Writing Clean and Maintainable Code
In the fast-paced environment of modern software development, programmers often face intense pressure to prioritize immediate delivery over structural elegance. When launching a brand-new feature or prototyping an early concept, getting code to execute without visible errors can feel like the ultimate milestone. Yet software engineering is rarely a one-off effort. Systems expand, business specifications shift, unanticipated edge cases emerge, and team rosters change over time.
When software is written haphazardly to meet short-term deadlines, it generates deep architectural friction that gradually drags future work to a crawl. Brittle foundations make everyday bug fixes treacherous, as a simple change in one file can inadvertently break unrelated modules across the application. Cultivating clean and maintainable code is therefore an essential engineering discipline, transforming source files into clear, modular assets that welcome modification, simplify onboarding, and save substantial time and money throughout a project's lifecycle.
Key takeaways
- Clean code reduces cognitive load by organizing complex operations into bite-sized, predictable, and modular components.
- Predictable naming conventions and descriptive identifiers allow source code to document its own intent without requiring bloated comments.
- Restricting functions and classes to a single, focused responsibility makes software dramatically easier to test, debug, and reuse.
- Comments should be reserved for explaining obscure formulas, external bug workarounds, or unusual business constraints rather than stating the obvious.
- Version control systems like Git provide a traceable historical record and an essential safety net for rolling back breaking changes.
The Mechanics of Readability and Cognitive Load
To grasp why clean code is indispensable, one must examine the fundamental distinction between what a machine requires and what human developers need. When a computer runs a software program, it executes compiled or interpreted machine instructions. The central processing unit does not register whether a function has meaningful variable names, orderly indentation, or disciplined separation of concerns; it executes tangled, convoluted routines just as swiftly as masterfully crafted code. Source code is written in human-readable programming languages precisely because people must conceive, review, maintain, and expand it over time.
Source code serves a dual purpose: instructing the computer what to do, and communicating to human developers how and why it is doing it.
At its core, clean code works by systematically minimizing cognitive load—the mental effort demanded of an engineer who is attempting to trace execution flow. When a program relies on cryptic abbreviations, endless procedures, and disorganized file trees, a developer must juggle dozens of variables, implicit states, and hidden side effects in their head simultaneously. This mental taxation drains energy, induces fatigue, and dramatically multiplies the chance of introducing fresh defects. Well-structured code breaks complex logic down into isolated, highly cohesive modules with obvious boundaries, allowing a reader to inspect a single component, verify its inputs and outputs, and proceed with absolute confidence.
Five Core Practices at a Glance
Applying clean code principles does not require rigid dogma, but it does require deliberate adherence to proven software engineering fundamentals. The following overview outlines the five foundational practices that turn messy scripts into sustainable codebases.
| Clean Code Principle | Primary Objective | Key Development Benefit | Common Pitfall to Avoid |
|---|---|---|---|
| Consistent Naming Conventions | Standardize identifier styles | Improves immediate visual recognition across files | Mixing formats unpredictably within a single project |
| Self-Documenting Code | Express purpose through syntax | Eliminates reliance on auxiliary documentation | Using generic, single-letter, or cryptic variables |
| Small Functions and Classes | Enforce single responsibilities | Isolates bugs and simplifies unit testing | Writing sprawling, multi-hundred-line monolithic blocks |
| Targeted Code Comments | Explain non-obvious reasoning | Provides critical context for complex edge cases | Paraphrasing what the syntax already shows |
| Disciplined Version Control | Track evolutionary history | Enables confident experimentation and easy rollbacks | Treating source repositories as casual backup drives |
Five Tips for Writing Clean and Maintainable Code
Building maintainable software requires intentional habits formed during daily implementation. By incorporating these five core strategies into your standard development workflow, you can ensure that your applications remain flexible, resilient, and straightforward to navigate.
Use Consistent Naming Conventions
Names constitute the foundational vocabulary of any software project. Every variable, constant, method, function, module, and class relies on an identifier to communicate what it represents. When naming conventions fluctuate erratically across a repository, the code feels disjointed and chaotic, forcing developers to pause repeatedly to parse stylistic inconsistencies instead of absorbing the core logic.
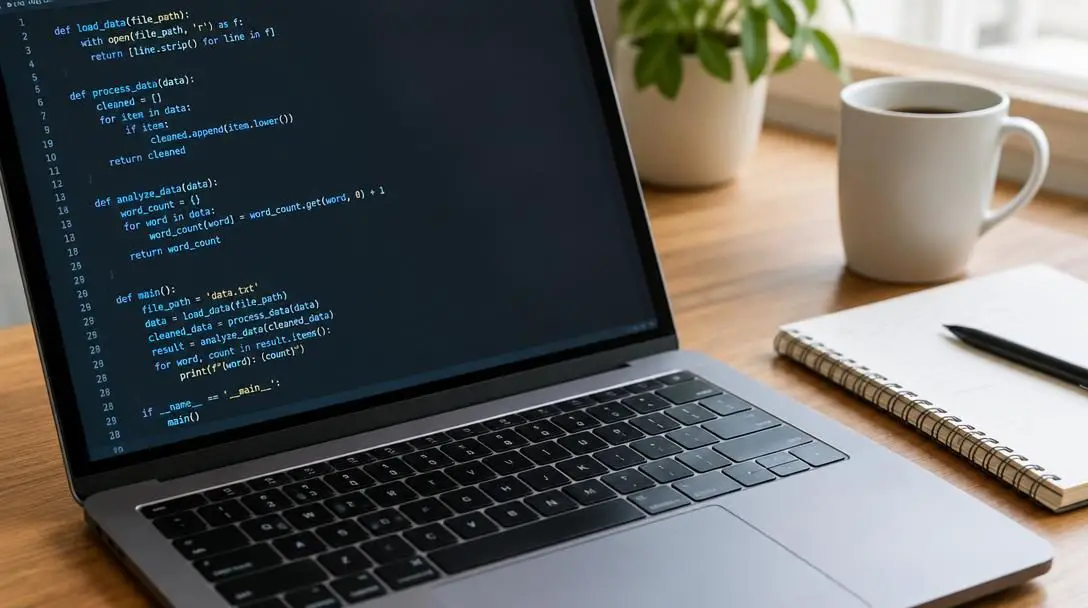
To establish visual coherence, select an established naming pattern appropriate for your environment and enforce it without exception. For example, if you adopt camel case (such as myVariable), apply it systematically to all corresponding entities. Other languages or team standards may prescribe snake case or pascal case. The specific casing style is often far less important than ensuring absolute uniformity across every directory. A predictable convention signals metadata at a glance, allowing readers to distinguish immediately between instantiated objects, static types, private helpers, or constant values.
Write Self-Documenting Code
Self-documenting code is software whose intent, behavior, and design boundaries are readily apparent solely from reading the implementation itself. In a self-documenting architecture, an engineer rarely needs to cross-reference external notes or hunt down inline comments to decipher how a data structure operates or what an algorithm computes.
The primary mechanism for authoring self-documenting code is selecting descriptive identifiers that accurately mirror real-world domain concepts. Developers should vigorously resist the urge to deploy generic names like temp, data, or single-letter indices like x in complex scopes. An identifier should transparently declare what it holds and how it contributes to the broader operational workflow. Choosing clear terminology benefits teammates reviewing your pull requests, but it equally protects your future self. Code written in the heat of a late-night deployment quickly becomes an impenetrable puzzle if variables fail to articulate their intended purpose months down the road.
Keep Functions and Classes Small
Modularity is the cornerstone of long-term software maintainability. Grouping business logic into sprawling, monolithic procedures creates deeply entangled dependencies, where modifying a single calculation on one page can trigger unpredictable side effects dozens of modules away. As a general design rule, functions and classes should do one thing only and do it exceptionally well.
When individual routines are kept small, testing and troubleshooting become radically more manageable. Isolating a logic defect within a concise routine spanning ten lines of code is straightforward and rapid. Conversely, diagnosing an intermittent runtime failure buried inside a thousand-line procedure demands exhaustive inspection of intermediate variables and shifting states. If you find a function accumulating multiple responsibilities—such as validating network payloads, transforming data models, and writing records to a database—it is time to refactor those secondary actions into separate, dedicated helpers that can be verified and reused independently.
Comment Your Code Where Necessary
While self-documenting syntax is the gold standard for expressing program flow, comments remain an invaluable asset when used with restraint. Source code excels at showing what an application is doing and how it executes. However, syntax alone cannot always reveal the historical context, external pressures, or non-obvious business rules that drove an architectural compromise.
Comments should be deployed to clarify why an obscure formula was chosen, document a workaround implemented to bypass an upstream vendor bug, or explain an unconventional edge-case requirement. What developers must avoid is over-commenting by simply restating the programming syntax in plain English. Cluttering source files with obvious line-by-line annotations adds visual noise, bloats the file size, and creates maintenance liabilities when comments inevitably become outdated after subsequent logic updates. When crafting annotations, keep them precise, meaningful, and directly focused on intent.
Use Version Control
Modern software engineering cannot function sustainably without disciplined source control. Codebases are living ecosystems that evolve continuously as bug patches are merged, performance optimizations are introduced, and new feature sets are rolled out. Attempting to manage revisions through manual backups, archived zip files, or shared network folders is an error-prone practice that invites catastrophic data loss.
Employing a modern version control system allows engineers to log granular, incremental changes over the lifespan of a software project. Because Git is the most popular and accessible version control system available today, mastering its basic branching, committing, and merging workflows gives teams a shared, transparent environment. Version control enables developers to experiment freely on isolated branches and effortlessly roll back to a known stable release if unexpected regressions occur in production. Furthermore, commit logs establish an accountable historical audit trail, recording precisely who implemented an adjustment, when it landed, and what specific problem it was designed to resolve.
A Practical Sequence for Refactoring Codebases
Transforming an unruly, legacy codebase into a clean, well-architected project can feel intimidating if attempted all at once. Rather than undertaking an unsafe, sweeping rewrite of the entire application, developers should apply steady, deliberate clean-up routines during everyday feature work.
- Conduct a focused naming audit across target modules, replacing obscure abbreviations, single-letter placeholders, and inconsistent casing styles with descriptive domain terminology.
- Analyze your longest functions and classes to identify mixed responsibilities, outlining which tasks belong to core business execution and which represent auxiliary chores.
- Extract secondary tasks—such as parameter parsing, logging, and data formatting—into compact, dedicated helper functions that perform a single job cleanly.
- Review existing inline comments to eliminate redundant descriptions of self-explanatory syntax while revising non-obvious explanations to record critical business context.
- Commit your refactored code systematically using Git, isolating structural improvements into discrete, well-documented changesets before introducing new application functionality.
Common Code Quality Mistakes to Avoid
When striving to improve source code structure, engineers sometimes swing between extremes, either neglecting organization entirely or applying patterns so rigidly that usability suffers. Recognizing these routine pitfalls helps keep development grounded and productive:
- Stating the obvious: Writing annotations that merely restate the literal code instruction adds cognitive clutter without delivering additional insight.
- Retaining commented-out dead code: Leaving obsolete logic commented out inside active files creates visual pollution; rely on your version control history instead.
- Cryptic or overly clever naming: Sacrificing clarity to save a few keystrokes produces unreadable logic that alienates collaborating teammates.
- Mixed stylistic conventions: Blending camel case, snake case, and ad-hoc abbreviations within the same directory prevents readers from forming reliable mental models.
- Monolithic, all-in-one routines: Allowing single functions to handle data retrieval, business calculations, and UI presentation creates rigid, fragile code that resists testing.
- Neglecting regular source control commits: Postponing commits or skipping branches eliminates the essential rollback safety net needed to refactor with confidence.
Scaling Quality with Team Standards and Automated Tooling
Once individual developers master the core habits of clean code, the next logical step is safeguarding those practices at the organizational level. Even well-intentioned teams can watch standards deteriorate if expectations are left to subjective interpretation. Establishing an explicit, unified style guide ensures that every contributor adheres to identical conventions regarding naming structures, file layouts, and architectural patterns.
To eliminate manual debate during peer reviews, modern teams frequently configure automated linters and code formatters. These developer tools parse source code prior to submission, flagging naming anomalies, catching unused imports, and applying uniform indentation rules automatically. By handing mechanical syntax enforcement over to automated pipelines, engineering teams can dedicate their mental energy during code reviews to high-level system architecture, logic integrity, and edge-case handling.
Clean code practices also yield massive advantages when implementing automated unit tests. Massive, highly coupled routines are notoriously painful to test because verifying a single calculation requires mocking vast networks of external states. Conversely, small functions that take clear inputs and return predictable outputs without side effects can be tested thoroughly in isolation. Writing clean, modular code builds an inherent testability into your software, allowing test suites to catch regressions before they ever impact end users.
Frequently asked questions
Does writing clean code slow down overall feature delivery?
While spending extra time selecting descriptive names and decomposing monolithic functions may feel slightly slower during the initial drafting phase, it drastically speeds up overall delivery across the project lifecycle. Unstructured code generates severe technical friction, leading to protracted debugging sessions, difficult onboarding, and frequent production breakages that consume far more engineering hours than thoughtful up-front design.
How short should a clean function ideally be?
There is no rigid mathematical limit on lines of code, but an ideal function should adhere strictly to the single-responsibility principle: doing one task and doing it well. If a routine spans dozens of lines and handles data validation, algorithmic transformation, and logging simultaneously, it should be refactored into smaller, specialized helper functions.
What is the difference between clean code and self-documenting code?
Self-documenting code is a specific subset of clean coding practices. It focuses on choosing clear, descriptive naming conventions and logical structural organization so that the purpose and mechanics of the software are immediately evident without requiring supplemental explanatory comments.
When should developers write comments instead of relying on self-documenting syntax?
Comments should be reserved for conveying the underlying intent and business context that syntax cannot show. This includes documenting workarounds for external software bugs, explaining non-standard formulas, or outlining unusual constraints dictated by external business rules. Comments should explain why something was implemented, not merely what the syntax does.
Why is version control considered a fundamental component of clean coding?
Version control systems like Git provide the safety net necessary to refactor and clean code fearlessly. Because every change is recorded and can be reverted immediately if errors arise, engineers can restructure brittle code, break down massive classes, and eliminate outdated logic without risking irreversible data loss or prolonged application downtime.
The bottom line
Writing clean and maintainable code is an essential investment in the health, stability, and longevity of any software project. By committing to uniform naming conventions, creating self-documenting identifiers, restricting functions to clear single responsibilities, deploying concise comments only where context demands it, and maintaining a disciplined version control history, developers establish an adaptable digital foundation. These core practices lower cognitive load, streamline collaboration, and safeguard applications against breaking changes, ultimately saving teams invaluable time, effort, and money as their software continues to evolve.