The Role of Correlations in Statistical Tests
Correlations represent one of the most fundamental concepts in modern statistics, describing the degree and orientation of association between two or more variables. Whether an investigation takes place in scientific research laboratories, corporate business analytics departments, public policy development groups, or clinical healthcare settings, examining how distinct factors shift in relation to one another is vital to decoding complex systems. Correlation analysis provides the quantitative bedrock necessary to detect patterns, evaluate underlying mechanics, and lay the groundwork for sophisticated experimental conclusions.
At the center of this practice is the correlation coefficient, a standardized numerical metric that measures both the strength and direction of a relationship. Rather than relying on subjective observation to note that two events occur alongside each other, the coefficient provides a bounded scale ranging strictly from -1 to 1. A score of 1 signals a perfect positive correlation, where variables climb or decline in direct tandem; -1 reflects a perfect negative correlation, where one variable climbs as the other drops; and 0 denotes the complete absence of a linear relationship. Selecting the correct measurement approach and properly situating correlation within broader statistical testing is essential for avoiding catastrophic errors in research design and data interpretation.
Key takeaways
- The correlation coefficient quantifies both the strength and direction of variable relationships on a fixed scale from -1 to 1.
- Analysts rely on three primary methodologies—Pearson's coefficient, Spearman's rank, and Kendall's tau—depending on data distribution, linearity, and sample size.
- Correlations serve as the structural framework for advanced modeling, including linear regression equations and experimental hypothesis testing.
- Extraneous confounding variables such as age or gender can distort outcomes unless corrected through statistical stratification or multivariate regression.
- High correlation among explanatory variables can directly reduce statistical power, impairing an investigator's ability to reject a false null hypothesis.
Core Methods for Measuring Statistical Correlation
Quantifying the connection between two metrics requires matching the mathematical calculation to the specific characteristics of the collected dataset. Factors such as whether data points are continuous or ranked, whether they follow a normal bell curve, and how vulnerable the sample is to extreme values dictate which correlation metric yields valid results. In standard statistical practice, three core techniques form the foundation of relationship analysis.
Pearson’s Correlation Coefficient
Pearson’s correlation coefficient is the standard technique deployed when evaluating continuous numeric variables that share a linear association. This approach inspects raw numbers directly and operates under the baseline assumption that the underlying data points conform to a normal distribution. Because it calculates variance based on the actual mathematical distance between values and their central mean, Pearson's measurement is exceptionally sensitive to extreme anomalies. A single unchecked outlier can dramatically distort the resulting score, either fabricating the illusion of a robust association or artificially suppressing a real, consistent trend.
Spearman’s Rank Correlation Coefficient
Spearman’s rank correlation coefficient bypasses the requirement of strict linearity by shifting the analytical focus from raw values to ordinal positions. Before computing the coefficient, the entire dataset is arranged and converted into ranks. This allows Spearman's test to evaluate monotonic relationships, which occur when two variables consistently move in identical directions even if that trajectory does not follow a straight line. Because monotonic progression relies solely on relative standing, Spearman's approach exhibits higher resilience against isolated extreme data points and serves as a dependable tool for non-normally distributed datasets.
Kendall’s Tau
Kendall’s tau offers an alternative rank-based metric that measures the structural association between pairs of observations based on concordance and discordance. Rather than comparing the absolute rank distances across the whole set, Kendall’s tau examines individual pairs of data points to evaluate whether their values increase together or shift in opposing directions. This pairwise computation makes Kendall's tau uniquely reliable when researchers work with very small sample sizes or handle datasets populated by frequent identical ranks, where other methods might produce inaccurate standard errors.
| Correlation Method | Primary Data Type | Assumed Relationship | Outlier Sensitivity | Ideal Sample Context |
|---|---|---|---|---|
| Pearson’s Coefficient | Continuous numerical data | Linear association | High sensitivity | Normally distributed datasets without extreme values |
| Spearman’s Rank | Ranked or continuous data | Monotonic association | Low sensitivity | Non-linear data or distributions with noticeable outliers |
| Kendall’s Tau | Ranked ordinal data | Concordant / discordant pairs | Low sensitivity | Small sample sizes and datasets containing tied ranks |
How Correlation Operates in Advanced Statistical Procedures
Correlation is rarely an isolated endpoint in formal statistical inquiry. Instead, it functions as the diagnostic and structural foundation for advanced modeling environments, predictive equations, and experimental evaluations. In regression analysis, which seeks to model the direct connection between an outcome variable and one or more predictive factors, correlation coefficients indicate whether an explanatory variable contains meaningful utility. If an independent factor generates a correlation coefficient hovering close to zero when paired with the dependent outcome, it supplies virtually no predictive power in standard linear regression formulas.
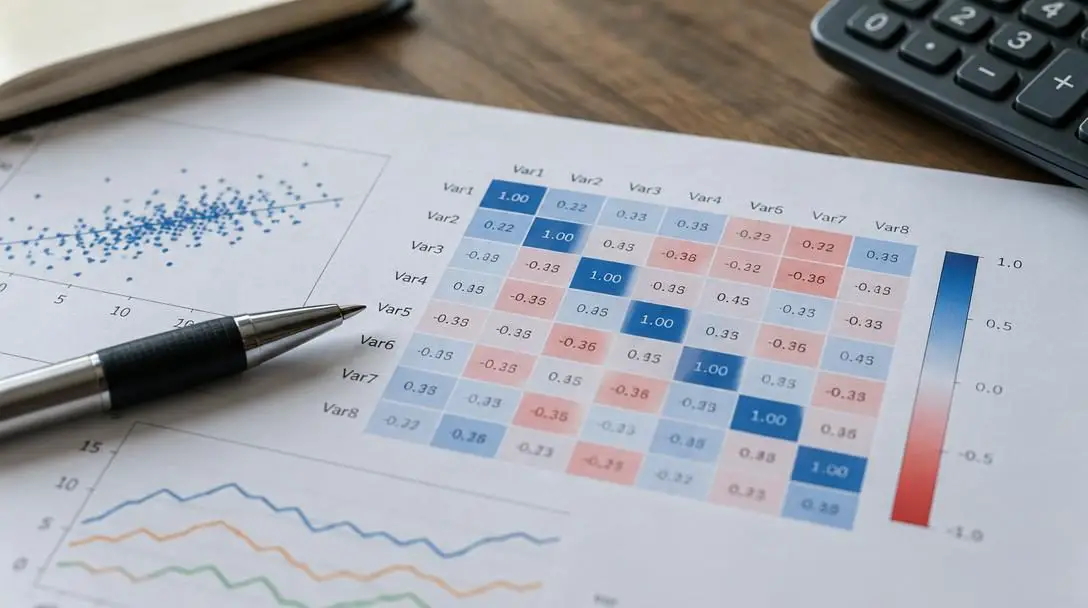
Conversely, strong positive or negative correlations validate the inclusion of specific variables in predictive models, enabling analysts to quantify how incremental shifts in one metric influence future values of another. For instance, in clinical medical trials, investigators frequently monitor the correlation between the administration of a drug formulation and the intensity of a symptom. Verifying this baseline correlation provides researchers with an empirical, objective measurement of association before they invest resources into complex multivariable equations.
A correlation coefficient provides a precise mathematical measure of association, but it never supplies proof that one metric drives the movement of another.
Correlations also play an essential role in hypothesis testing, where analysts examine whether observed differences between groups are statistically meaningful or simply artifacts of random chance. When evaluating two groups, the magnitude of their correlation provides evidence regarding the cohesion of their relationship. However, high correlations can complicate the testing environment by threatening the statistical power of an assessment. Power describes the probability that a statistical test will correctly reject a null hypothesis when that hypothesis is truly false. When independent explanatory variables correlate heavily with each other, they generate computational static that inflates variance, obscures individual variable contributions, and drastically reduces the test's power, sometimes masking real underlying effects.
Addressing Bias and Confounding Variables
A primary hazard in correlation analysis is the presence of confounding variables. In any experimental or observational study, bias can emerge when extraneous factors share simultaneous correlations with both the designated treatment and the measured outcome. When these secondary variables go unmonitored, researchers face the risk of attributing changes in an outcome to an experimental intervention when the observed variation was actually driven by an outside element.
Consider a medical study designed to evaluate the therapeutic efficacy of two distinct medical interventions. If the allocation of treatments is unintentionally correlated with demographic attributes such as age or gender—such as if younger patients predominantly receive the first treatment while older cohorts receive the second—the baseline health trajectories associated with biological age become entangled with the pharmaceutical effects of the drug. The calculated correlation between the treatment and patient recovery rates will be compromised by systemic bias.
To eliminate this threat and maintain study validity, analysts implement two primary corrective mechanisms:
- Statistical Stratification: Researchers divide the primary dataset into homogenous sub-categories based on the confounding attribute. By comparing the treatment and outcome strictly within isolated age brackets or gender groupings, the confounding correlation is neutralized across groups.
- Multivariate Regression Analysis: Rather than evaluating the treatment in isolation, analysts incorporate the extraneous elements directly into the regression framework as explanatory covariates. This allows the mathematical equation to hold factors like age and gender constant, isolating the unique, unpolluted relationship between the primary variables.
Step-by-Step: Incorporating Correlations into Statistical Workflows
Executing correlation analysis inside an empirical research project requires methodical execution. Skipping exploratory diagnostics often leads to flawed assumptions and invalidated test conclusions. Following a structured sequential workflow guarantees rigorous data handling from preparation to final reporting.
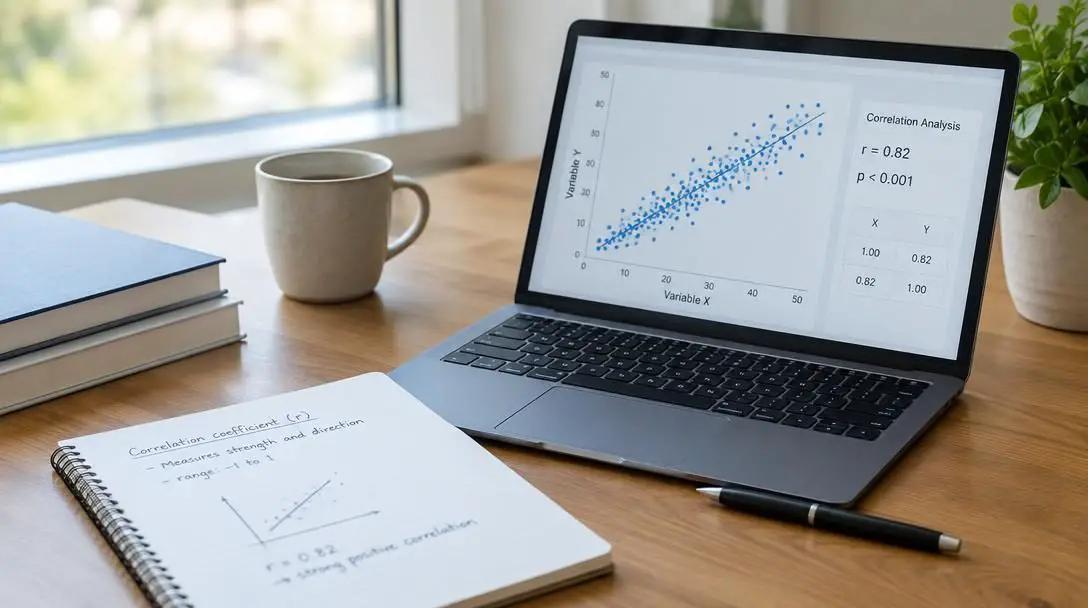
- Define the Analytical Scope: Clearly designate the primary independent variables and the dependent outcome measures. Determine whether the ultimate objective is descriptive association, predictive regression modeling, or hypothesis testing between comparative groups.
- Inspect and Characterize Data Formats: Audit the metrics to confirm whether they consist of continuous intervals, ranked categories, or ordered scales. Evaluate whether the distribution fulfills normality criteria to decide between Pearson’s parametric formula or non-parametric alternatives like Spearman’s rank and Kendall’s tau.
- Compute the Baseline Correlation Coefficient: Run the selected calculation on variable pairs to identify their numerical standing between -1 and 1. Record both the magnitude and trajectory to verify whether a preliminary association exists.
- Scan for Inter-Variable Correlation: In datasets containing multiple explanatory factors, calculate correlations among the independent variables themselves. Flag high associations that could introduce computational noise or degrade the statistical power of subsequent tests.
- Screen for Extraneous Confounders: Identify whether external background variables, such as participant age, gender, or environmental traits, share systematic correlations with the primary intervention and the target outcome.
- Deploy Corrective Adjustments: If confounding patterns appear, implement stratification across subgroups or transition into multivariate regression equations to mathematically hold extraneous covariates constant.
- Synthesize Findings Without Causal Leaps: Interpret the resulting coefficients as verified descriptions of mathematical movement. Document the strength of the association clearly without claiming that one variable directly causes changes in the other.
Frequent Pitfalls in Correlation Analysis
Because correlation calculations are straightforward to run using modern statistical software, analysts can easily misuse their outputs. Avoiding common interpretive and methodological errors preserves the integrity of experimental findings.
- Assuming Causality from Association: The most prevalent error in statistical evaluation is treating high correlation as evidence of cause and effect. Two variables may rise and fall together due to random coincidence or because a hidden, unmeasured third variable influences both metrics simultaneously.
- Overlooking Distorting Outliers: When deploying Pearson’s correlation, rare anomalous data points exert disproportionate leverage on the mathematical mean. A single extreme outlier can elevate a negligible relationship into a statistically significant one or flatten a genuine association.
- Failing to Control for Confounders: Neglecting to identify demographic or environmental traits that correlate with both independent and dependent factors introduces severe bias, attributing therapeutic or procedural success to the wrong mechanisms.
- Disregarding Reductions in Test Power: Ignoring intense correlations among independent predictor variables suppresses test power. This oversight frequently leads to false-negative conclusions, where real and meaningful effects fail to reach statistical significance.
- Misapplying Linear Metrics to Curved Relationships: Pearson’s correlation assumes a straight-line pattern. When two factors exhibit a non-linear or U-shaped association, Pearson calculations may return a value near zero, leading analysts to mistakenly claim that no relationship exists.
Strategic Next Steps After Computing Correlations
Arriving at an empirical correlation coefficient marks the beginning of deeper statistical investigation rather than its final conclusion. Once the direction and intensity of an association are confirmed, analysts must decide how to advance the research pipeline effectively.
When correlation indicates a robust, reliable link between variables, the natural progression is to construct regression models. This transition transforms observational data into actionable equations, allowing practitioners to project future outcomes based on incremental changes in input factors. However, if baseline correlation scans identify that extraneous demographic attributes correlate with interventions, the entire experimental framework may require revision. Researchers must determine whether post-hoc statistical corrections like multivariate regression are sufficient or if physical adjustments to sample collection and balanced participant recruitment are required.
Finally, if an investigation seeks to establish true causal links, correlation coefficients alone can never serve as definitive proof. Analysts must transition from observational data collection to rigorous randomized controlled trials, longitudinal time-series analyses, or mechanistic laboratory research designed specifically to isolate causation from mathematical correlation.
Frequently asked questions
What does a correlation coefficient of zero mean?
A correlation coefficient of zero indicates that there is no linear relationship between the two variables being evaluated. However, it does not rule out the possibility of a strong non-linear or curved association, which requires visual inspection or non-linear modeling tools to identify.
How does correlation differ between Pearson and Spearman methods?
Pearson’s coefficient measures the linear association between continuous, normally distributed variables using raw mathematical values. Spearman’s rank coefficient measures monotonic trends across continuous or ranked data by converting values into ordinal ranks, making it less sensitive to extreme outliers.
Can high correlation between variables damage a statistical test?
Yes. When independent predictor variables are highly correlated with each other, they introduce computational redundancy that inflates variance and reduces the statistical power of the test. This can make it difficult to detect real differences, leading to false-negative outcomes.
Why does correlation not prove causation?
Correlation only demonstrates that two variables change values in a coordinated pattern. It does not establish which variable moved first, nor does it exclude the influence of an unmeasured confounding third variable that might be driving the changes observed in both metrics.
How do researchers eliminate bias from confounding variables?
Researchers manage confounding variables through methods like statistical stratification, which breaks data into balanced subgroups based on the confounding attribute, or multivariate regression analysis, which holds outside variables constant mathematically.
The bottom line
Correlation analysis serves as an indispensable tool across statistical disciplines, providing an objective framework to quantify how variables behave in relation to one another. From foundational assessments in medical research to predictive forecasting in regression models, the correlation coefficient supplies critical insights into directional trends and association strength. However, maintaining scientific integrity requires choosing the right mathematical method, actively screening for confounding elements, protecting statistical power, and resisting the urge to mistake correlation for causation. When used with precision, correlation analysis paves the way for accurate modeling, robust experimental design, and dependable scientific conclusions.